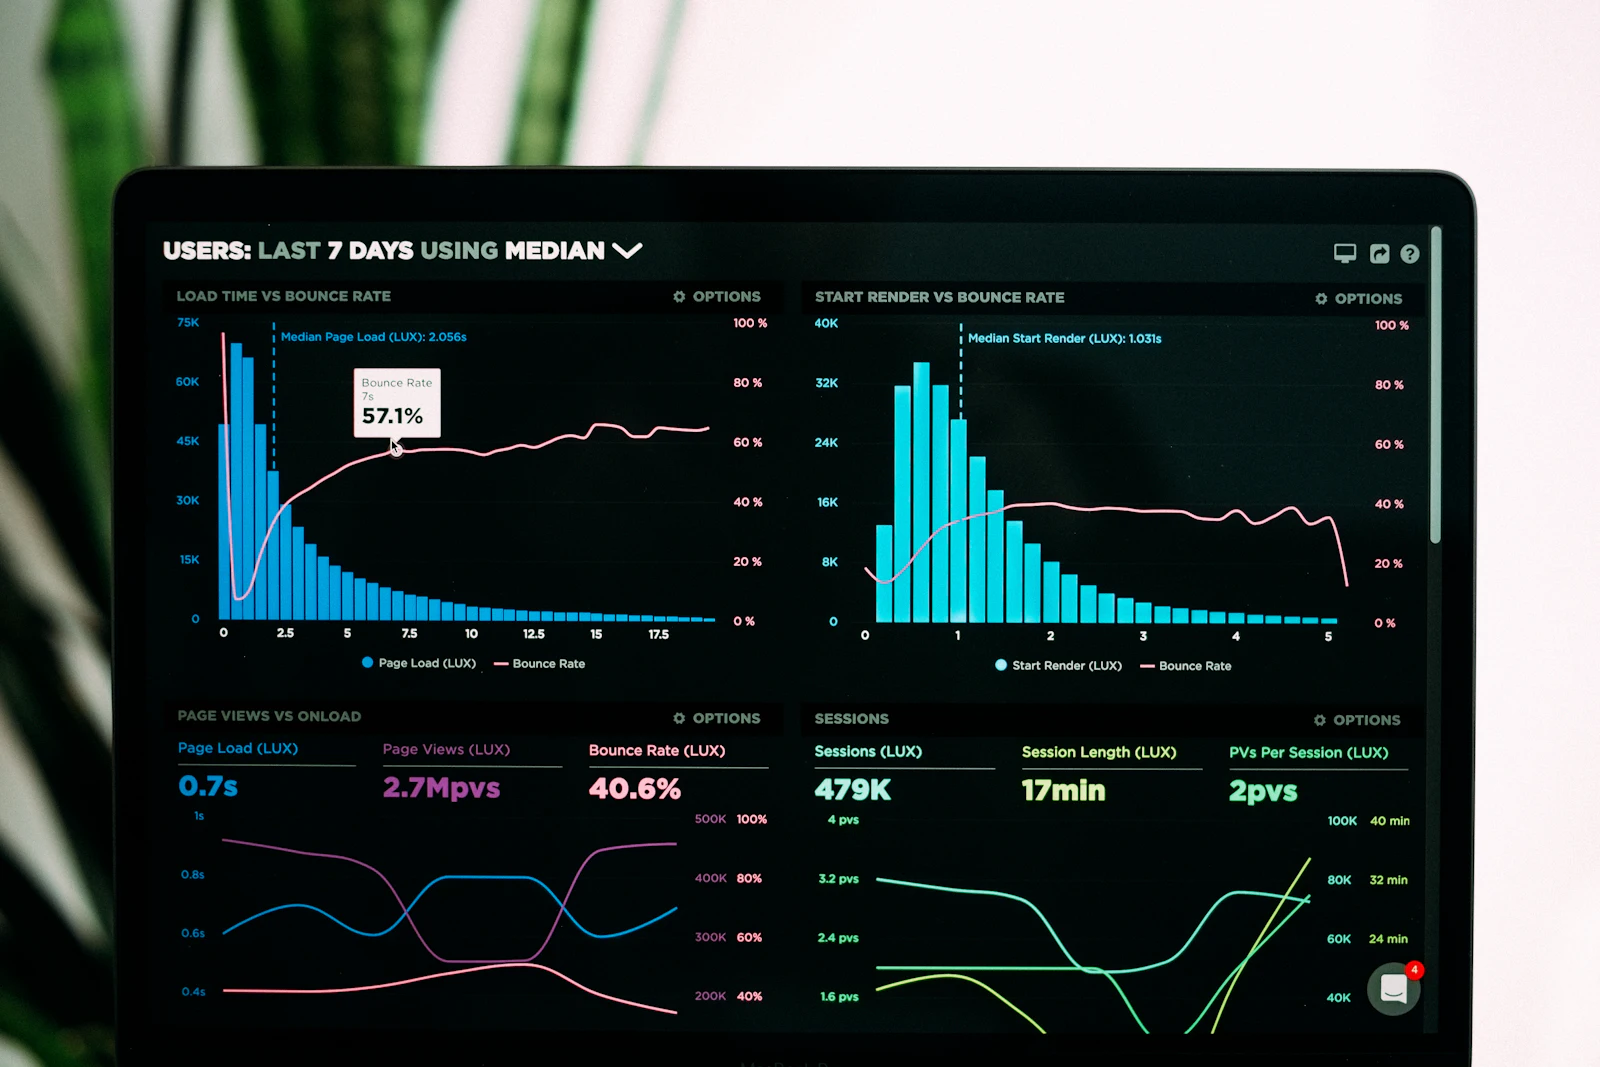
Infrastructure support: we take over a system that already runs
The system works and has to keep working. We take it under supervision: find out what runs where, close the gaps in backups and monitoring, then handle updates and incidents month after month. It does not matter who built it.
When you need this
- 1
The system runs, but nobody on the team is responsible for the servers
- 2
The contractor or engineer who built it has left, and there is no documentation
- 3
Updates have not been installed for a long time because everyone is afraid to touch anything
- 4
You learn about outages from your users
- 5
Backups are supposedly made, but nobody has ever restored from one
What's included
Audit and inventory
We list servers, services, access, scheduled jobs, certificates and backups. You get a map of the system and a list of risks in order of severity.
Monitoring and alerts
Metrics, logs and availability checks for every service. Alerts come to us and, if you want, to your Telegram or Slack.
Updates and patches
The OS, Kubernetes, databases and base images are updated on a schedule: staging first, then production, with a way back.
Incident response
We receive the alert and restore the service. Then we write down what happened, why, and what was changed so it does not repeat.
Backups and restore drills
Backups run on a schedule and are stored off the server. We regularly restore them into a test environment to prove they work.
Monthly report
What was done, which incidents happened, how resources are used and what we recommend doing next.
The whole system on one screen
Service health, traffic, deploys and alerts — the dashboards we set up for every project.
Service overview
- Services
- 12
- Healthy
- 12 / 12
- Deploys today
- 7
- Open alerts
- 0
Requests per second
All services, 5 min average
p95 latency, ms
Alarm threshold 250 ms
Service health
| Service | Status | Pods | CPU |
|---|---|---|---|
| api-gateway | Healthy | 6 / 6 | 41% |
| billing | Healthy | 3 / 3 | 28% |
| worker-pool | Healthy | 9 / 9 | 63% |
| postgres-main | Healthy | 2 / 2 | 35% |
Recent deploys
- api-gatewayv2.14.112 min ago
- worker-poolv1.9.01 h ago
- billingv3.2.43 h ago
Illustration with sample data. Every project gets dashboards built around its own services.
How the work goes
- 1
Access and audit
You grant read-only access. We describe the real state of the system and what is at risk.
- 2
Clean-up
The critical gaps go first: backups, monitoring, access, expiring certificates. This stage has a fixed price.
- 3
Supervision
The system goes onto monthly support with a response time and coverage hours agreed in advance.
- 4
Reports and improvements
You get a report every month. Larger changes are proposed separately and done only after you agree.
Questions
- Linux
- Kubernetes
- Helm
- Terraform
- PostgreSQL
- Grafana
- VictoriaMetrics
- Loki
- Alertmanager
- AWS EC2
- AWS EKS
- Hetzner
Describe the task — get a plan and a price
Write what you have and what you need. We answer within one business day with questions or a concrete proposal.